llm-roundtable
A multi-LLM council for autonomous coding agents. When your agent would stop and wait for you, Claude, GPT, Grok and Gemini (plus an opt-in free OpenCode model) gather evidence, cross-examine each other anonymously and vote.
Install
npx skills add dinhkarate/llm-roundtable --skill llm-roundtable   # Agent Skill for every agent on this machine
npx llm-roundtable doctor --probe                                  # which seats can sit
npx llm-roundtable run --brief brief.md --default C                # last line: VERDICT: B (council)

# Claude Code only, optional: the same skill as a plugin (pick one install path, not both)
/plugin marketplace add dinhkarate/llm-roundtable
/plugin install llm-roundtable@llm-roundtable
Why a council, and why a vote
- Four vendors (five with OpenCode), your subscriptions. Drives the claude, codex, grok, agy and opencode CLIs. No API keys, no MCP server.
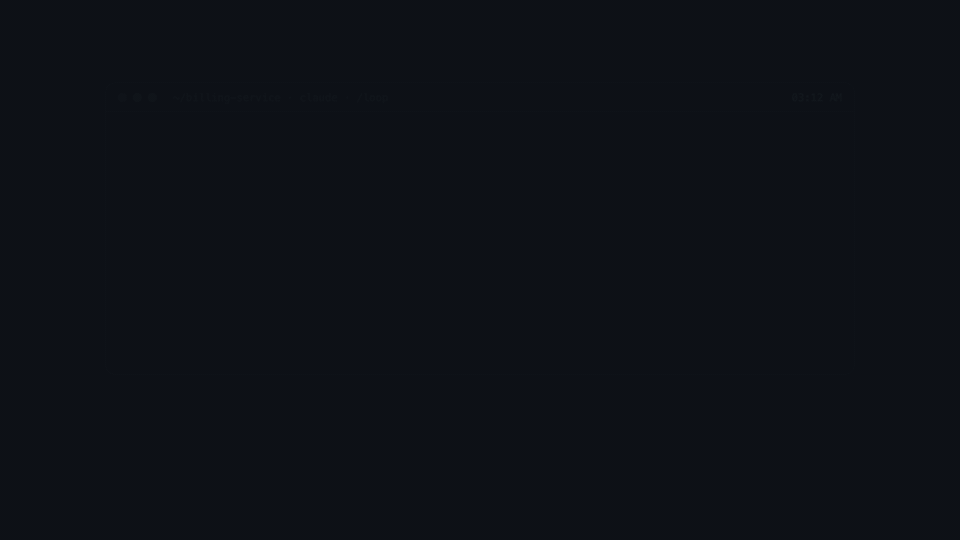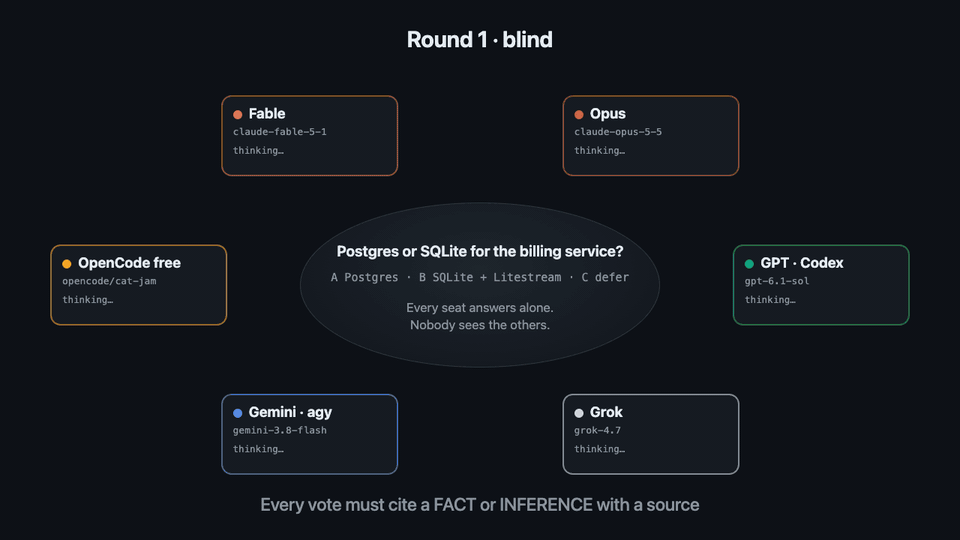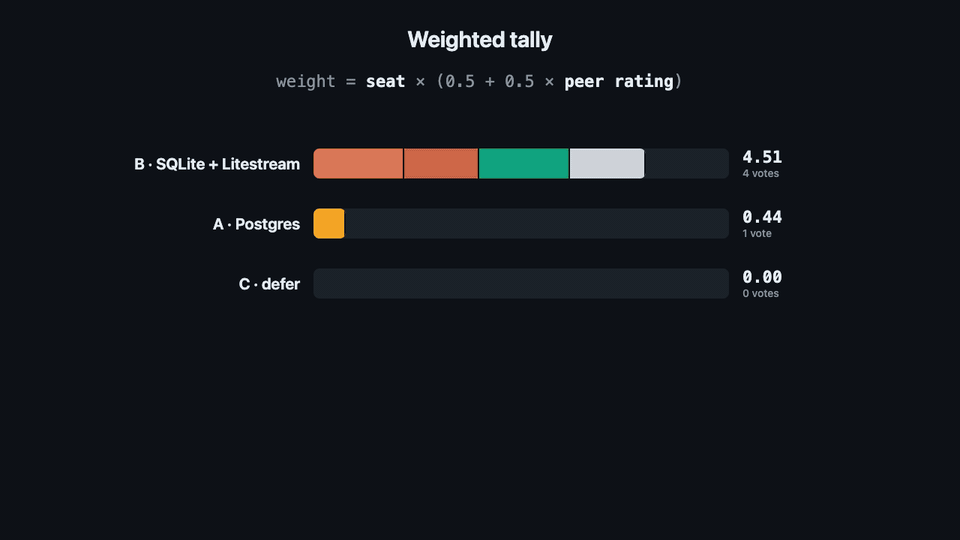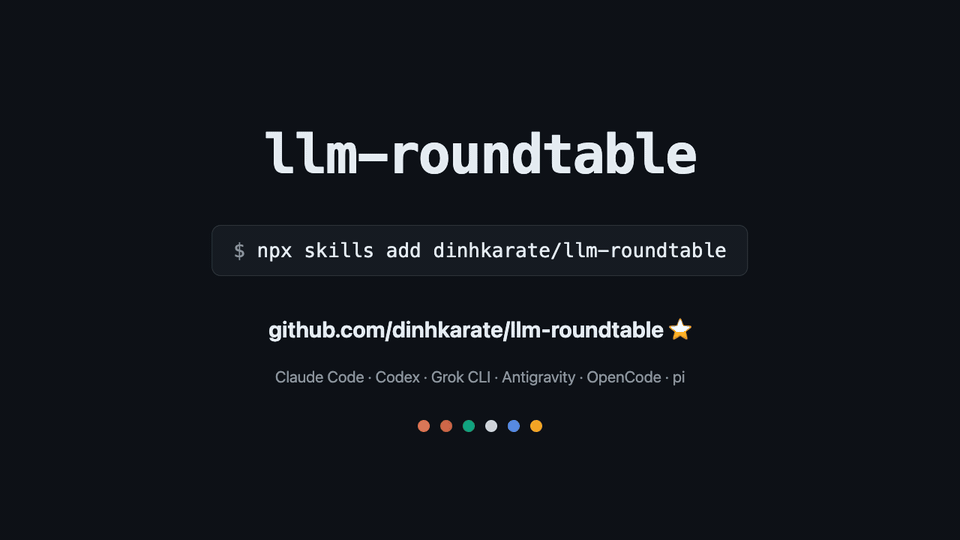
- Evidence or it does not count. Every ballot needs a sourced FACT or INFERENCE; peers rate it 0-2 and the rating scales the vote.
- Anonymous cross-examination. Round 2 shows positions as M1..Mn, shuffled, in fresh sessions, which reduces sycophancy and self-bias (ACL 2026).
- A vote, not a chairman. Most of the benefit of multi-agent debate comes from voting (Debate or Vote, NeurIPS 2025), so the verdict is arithmetic.
- Never blocks. One-level fallback per model family, then UNATTENDED; ties go to the Fable seat; undecided falls back to your safe default.
- Read-only and sandboxed by default. Publishing tools removed, each seat keeps only its own CLI's credentials, workspace fingerprinted after every round. The opt-in OpenCode seat is not sandboxed.
Works from
Claude Code
Full council, or the duo preset (Fable vs Opus) with only Claude installed.
Codex CLI
solo-codex preset plus a free OpenCode model for a second vendor.
Grok CLI · Antigravity · OpenCode · pi
Any agent with a shell. Add new CLIs with a few lines of JSON.
FAQ
- What is an LLM council?
- A group of language models that answer the same question independently, then combine their answers through review and voting.
- How long does a council take?
- About 10 model calls (5 seats × 2 rounds), typically 5-20 minutes. One blind round halves it.
- Can it review a pull request?
- Yes:
--mode review --workspace .gives read-only repo access and the options become APPROVE / CHANGES / REJECT. - Will it change my code?
- Not with the default seats: they are read-only, and a changed workspace marks the run TAINTED with no verdict. The opt-in OpenCode seat is not sandboxed.